- 16 Posts
- 40 Comments

The problem is there will be multiple solutions that result in the same hash (collisions), but only one of them will be correct
And it would take an extremely long time to find them all, I don’t even think a modern GPU could do it in a lifetime

 2·11 days ago
Thanks! I’ve seen way too many people on Reddit that obviously do not know about --n-cpu-moe because they always think you need enough VRAM for the entire model
You can set a maximum number of slots and it will automatically unload to load a different model, I just set mine to 1 slot so there’s only 1 model loaded at a time

I only use Qwen for Zoo Code, when chatting I just use Gemma


It’s MoE so you can use --n-cpu-moe
https://lemmus.org/post/24235317
Low number of active parameters (6B) means you don’t need much VRAM to get decent speeds
Number of Parameters: 125B with 6B activated, plus 51B n-gram embedding and 4B MTP
I bet you could run this in Q4 on 96GB RAM and 16GB VRAM, maybe even less. The benchmark scores seem good, beating 27b and DeepSeek Flash.
The n-gram embeddings sound very similar to Gemma 4 e4b embeddings. Need llama.cpp to support streaming n-grams from SSD, mmap would be less efficient than having explicit support.
GGUFs are starting to be available now

Yeah Ornith 1 35b seemed pretty good when I tried it, haven’t tried 1.5 yet. The only one from the 1.5 series I tested so far was 9b and it seems to punch above its weight

Have you tried Kat Coder? It’s also a fine-tune of Qwen 35b and I’ve heard good things about it
 7·24 days ago
Yeah that one was over a torrent site, I think nyaa.si
https://lemmy.ca/post/69262372
https://www.techspot.com/news/113446-years-long-investigation-unmasked-major-torrent-pirate-how.html
8GB VRAM RTX 3070 + 32 GB DDR5 + 1TB NVMe SSD - AMD Ryzen 5 7600X CPU - putting this here in case it’s substantially better than the BC-250
Yes this can run Qwen 3.6 35b-a3b pretty nicely! And they might be releasing an updated version of that soon. Your BC-250 only has 16GB total which is not enough for 35b.
I also have 32GB RAM and 8GB VRAM, my computer is a little slower than yours, see my guide: https://lemmus.org/post/24235317
For the BC-250 you might try smaller models like Ling 3.0 Tiny, Ornith 1.5 9b, or Gemma 4 12b QAT
For your 8GB RAM devices, you can run Gemma 4 e4b QAT, Qwen 3.5 4b, or maybe Ling 3.0 Tiny
I’m a noob to local LLMs.
Use Unsloth Desktop or llama.cpp. Then you can connect Zoo Code to it, that’s a VSCode extension which I like for programming with my local LLMs.
They don’t tell us things lol. All they said was
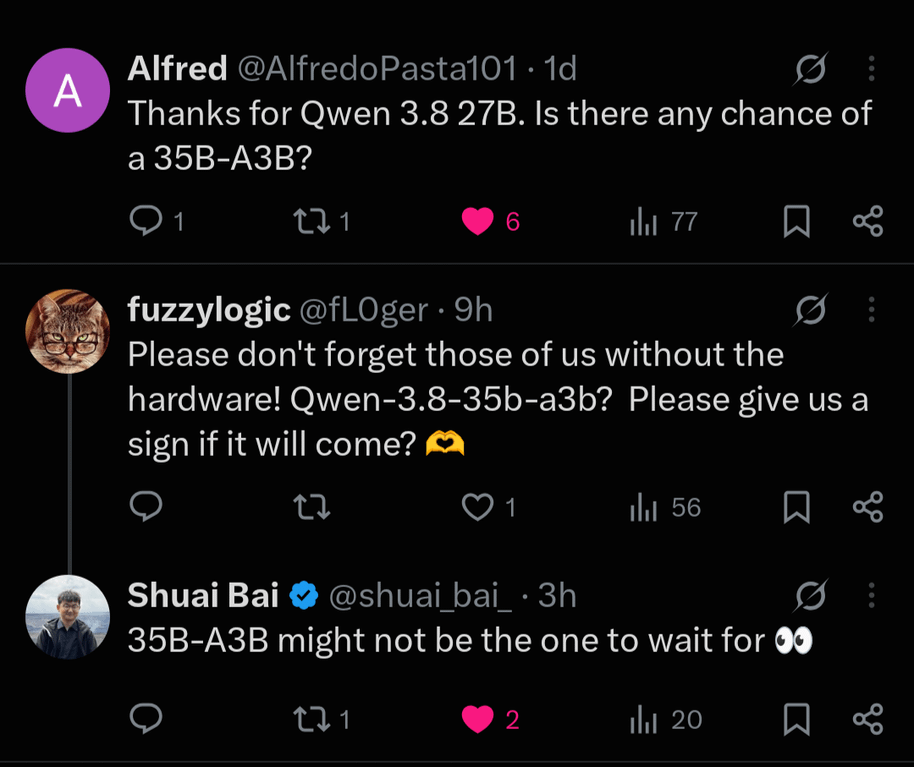
Which sounds like there’s something “better” coming, but doesn’t deny the possibility of 35b-a3b. Which is weird because “better” is subjective and depends on your hardware. It could be smaller and smarter than 3.6 35b, but then people are gonna ask for a 3.8 35b because it should be even smarter.
They have a graph, differences are tiny at that high end

I feel like Ornith 1.0 9b was the best coding model at that size (since Qwen has neglected that size). Maybe now Ling Tiny is better but I’m curious to try Ornith 1.5
 3·1 month ago
I would suggest using llama.cpp instead of Ollama, or maybe Unsloth Studio
Sounds like you could just replace the template to fix it, there’s a popular Qwen fixed template on hugging face, try that
https://huggingface.co/froggeric/Qwen-Fixed-Chat-Templates/blob/main/chat_template.jinja
 1·1 month ago
llama.cpp is way better than Ollama. If you want a GUI then use Unsloth Desktop
Use llama.cpp or Unsloth Desktop with an uncensored/abliterated model. Gemma 4 models are great for chats. But I don’t think it would give you better answers than the people in this community. And I would be too afraid to give it a web search MCP while asking it questions about piracy.
A better place to ask about AI stuff would be !localllama@sh.itjust.works


Well the hashes are always much smaller than the actual data, otherwise downloading the hashes would take just as long as downloading the data lol.
So 16KB blocks means 131072 bits per block, subtract the 256 bit hash size and that means 2^130816 hash collisions
That’s a lot lol, you’ll never find which one is the correct one. Even if you instantly had a list of all values that match the desired hash, you’d have to check them all and somehow determine which one was correct.